

文档解析
接口描述
【活动】新客专享福利,文档解析、文档解析(PaddleOCR-VL) 低至9元/千页
文档解析支持对doc、pdf、图片、xlsx等18种格式文档进行解析,输出文档的版面、表格、阅读顺序、标题层级、旋转角度等信息,支持中、英、日、韩、法等20余种语言类型,可返回Markdown格式内容,将非结构化数据转化为易于处理的结构化数据,识别准确率可达 90% 以上。如希望快速可视化体验效果,可登录智能文档分析平台,一键上传文档,在线测试;在线工具和API服务的额度共享互通。
文档解析API服务为异步接口,需要先调用提交请求接口获取 task_id,然后调用获取结果接口进行结果轮询,建议提交请求后 5~10 秒轮询。提交请求接口QPS为2,获取结果接口QPS为10。
在线调试
您可以在 示例代码中心 中调试该接口,可进行签名验证、查看在线调用的请求内容和返回结果、示例代码的自动生成。
为方便您更好地使用文档解析服务,我们设立了专属交流群。您可通过下方二维码入群:

提交请求接口
请求说明
请求示例
HTTP 方法:POST
请求URL: https://aip.baidubce.com/rest/2.0/brain/online/v2/parser/task
URL参数:
| 参数 | 值 |
|---|---|
| access_token | 通过API Key和Secret Key获取的access_token,参考“Access Token获取” |
Header如下:
| 参数 | 值 |
|---|---|
| Content-Type | application/x-www-form-urlencoded |
Body中放置请求参数,参数详情如下:
请求参数
| 参数 | 是否必选 | 类型 | 可选值范围 | 说明 |
|---|---|---|---|---|
| file_data | 和file_url二选一 | string | - | 文件的base64编码数据:-版式文档:pdf、jpg、jpeg、png、bmp、tif、tiff、ofd、ppt、pptx-流式文档:doc、docx、txt、xls、xlsx、wps、html、mhtml文档大小不超过50M,其中PDF文档最大支持2000页若文档大小超过50M,须从file_url方式上传。优先级: file_data > file_url,当file_data字段存在时,file_url字段失效 |
| file_url | 和file_data二选一 | string | - | 文件数据URL,URL长度不超过1024字节,支持单个URL传入。PDF文档大小不超过300M,非PDF文档大小不超过50M,其中PDF文档最大支持2000页优先级: file_data > file_url,当file_data字段存在时,file_url字段失效请注意关闭URL防盗链 |
| file_name | 是 | string | - | 文件名,请保证文件名后缀正确,例如 申请书.pdf |
| recognize_formula | 否 | bool | True/False | 是否对版式类型文档进行公式识别 |
| analysis_chart | 否 | bool | True/False | 是否对统计图表进行解析 |
| angle_adjust | 否 | bool | True/False | 是否对图片进行矫正 |
| parse_image_layout | 否 | bool | True/False | 是否返回文档中的图片位置信息 |
| language_type | 否 | string | - | 识别语种类型,默认为 CHN_ENG,可选值如下:-CHN_ENG:中英文 - JAP:日语- KOR:韩语- FRE:法语- SPA:西班牙语- POR:葡萄牙语- GER:德语- ITA:意大利语- RUS:俄语- DAN:丹麦语- DUT:荷兰语- MAL:马来语- SWE:瑞典语- IND:印尼语- POL:波兰语- ROM:罗马尼亚语- TUR:土耳其语- GRE:希腊语- HUN:匈牙利语- THA:泰语- VIE:越南语- ARA:阿拉伯语- HIN:印地语 |
| switch_digital_width | 否 | string | - | 是否对数字进行全半角转换,默认为 auto,可选值如下:-auto:不转换,按模型识别结果输出 - half:将所有的符号转换为半角输出- full:将所有的符号转换为全角输出 |
| html_table_format | 否 | bool | True/False | 是否将识别出的表格转换为 HTML 格式返回,default=True |
| return_doc_chunks | 否 | dict | - | 是否返回文档切分后的片段数据(如按语义、字数、标点)。如有需要,可按下方说明进行传参 |
| + switch | 否 | bool | True/False | 是否进行文档内容切分,default=False |
| + split_type | 否 | str | - | 切分方式,目前支持两种,default=chunk - chunk:按照「chunk_size」来切 - mark:按照「separators」来切 |
| + separators | 否 | list |
- | 切分标点,default=['。', ';', '!', '?', ';', '!', '?'],split_type=mark时生效 |
| + chunk_size | 否 | int | - | 切分块的大小,chunk_size=-1时,表示按照语义自动切分,不限定块的大小;chunk_size>0时,表示按照字符长度切 |
| page_filter | 否 | string | - | 只解析指定页,页码从 0 开始。格式:4(单页)、0-2(闭区间)、0-2,4,7-9。流式文档不支持。新增 |
| need_pdffile_data | 否 | bool | True/False | 查询成功时额外返回整份 PDF 的 pdf_file_url。default=False 新增 |
| detect_seal | 否 | bool | True/False | 检测印章,输出 type=seal 的框。default=False 新增 |
| recognize_seal | 否 | bool | True/False | 识别章面文字;开启后自动打开 detect_seal。default=False 新增 |
| erase_seal | 否 | bool | True/False | 擦除印章。优先级高于章面识别;与 recognize_seal 同时开时保留检测框、去掉文字。建议不要和章面识别同时开。default=False 新增 印章参数组合说明: detect_seal=false、recognize_seal=false、erase_seal=false → 不做印章 detect_seal=true、recognize_seal=false、erase_seal=false → 只有检测框 recognize_seal=true、erase_seal=false → 检测 + 章面文字(自动打开检测) erase_seal=true → 擦除章面;若同时识别,框还在、文字去掉 |
| erase_watermark | 否 | bool | True/False | 去水印仅用于识别前增强,返回的页面图 / PDF 不会去掉水印。default=False 新增 |
| parse_image_valid_ratio | 否 | float | - | 图片占页面面积低于该阈值则丢弃,不写入 images。default=0.1 新增 |
| word2pdf | 否 | bool | True/False | 将 Word 转成 PDF 再按版式解析;转完后可以使用 page_filter。default=False 新增 |
| traditional2simplified | 否 | bool | True/False | 繁体转简体。default=False 新增 |
请求代码示例
提示:使用示例代码前,请记得替换其中的示例Token、文档地址或Base64信息。
1import requests
2import os
3import base64
4
5
6def create_task(url, file_path, file_url):
7    """
8    Args:
9        url: string, 服务请求链接
10        file_path: 本地文件路径
11        file_url: 文件链接
12    Returns: 响应
13    """
14    # 文件请求
15    with open(file_path, "rb") as f:
16        file_data = base64.b64encode(f.read())
17    data = {
18        "file_data": file_data, #与file_url二选一,只传 URL 时不要带 file_data
19        "file_url": file_url,
20        "file_name": os.path.basename(file_path)
21    }
22
23    # 文档切分参数,非必传
24    # return_doc_chunks = json.dumps({"switch": True, "chunk_size": -1})
25    # data["return_doc_chunks"] = return_doc_chunks
26
27    headers = {'Content-Type': 'application/x-www-form-urlencoded'}
28
29    response = requests.post(url, headers=headers, data=data)
30    return response
31
32if __name__ == '__main__':
33    request_host = "https://aip.baidubce.com/rest/2.0/brain/online/v2/parser/task?" \
34                   "access_token={token}"
35    file_path = "./test.pdf"
36    response = create_task(request_host, file_path, "")
37    print(response.json())
返回说明
返回参数
| 字段 | 类型 | 说明 |
|---|---|---|
| log_id | uint64 | 唯一的log id,用于问题定位 |
| error_code | int | 错误码 |
| error_msg | string | 错误描述信息 |
| result | dict | 返回的结果列表 |
| + task_id | string | 该请求生成的task_id,后续使用该task_id获取解析结果 |
返回示例
成功返回示例:
1{
2    "error_code": 0,
3    "error_msg": "",
4    "log_id": "10138598131137362685273505665433",
5    "result": {
6        "task_id": "task-3zy9Bg8CHt1M4pPOcX2q5bg28j26801S"
7    }
8}失败返回示例(详细的错误码说明见API文档-错误码):
1{
2    "error_code": 282003,
3    "error_msg": "missing parameters",
4    "log_id": "37507631033585544507983253924141",
5    "result": "null"
6}
获取结果接口
在线调试
您可以在 示例代码中心 中调试该接口,可进行签名验证、查看在线调用的请求内容和返回结果、示例代码的自动生成。
请求说明
请求示例
HTTP 方法:POST
请求URL: https://aip.baidubce.com/rest/2.0/brain/online/v2/parser/task/query
URL参数:
| 参数 | 值 |
|---|---|
| access_token | 通过API Key和Secret Key获取的access_token,参考“Access Token获取” |
Header如下:
| 参数 | 值 |
|---|---|
| Content-Type | application/x-www-form-urlencoded |
Body中放置请求参数,参数详情如下:
请求参数
| 参数 | 是否必选 | 类型 | 说明 |
|---|---|---|---|
| task_id | 是 | string | 发送提交请求时返回的task_id |
请求代码示例
提示:使用示例代码前,请记得替换其中的示例Token、task_id。
1import requests
2
3def query_task(url, task_id):
4    """
5    Args:
6        url: string, 请求链接
7        task_id: string, task id
8    Returns: 响应
9    """
10    data = {
11        "task_id": task_id
12    }
13    headers = {'Content-Type': 'application/x-www-form-urlencoded'}
14    print(url)
15    response = requests.post(url, headers=headers, data=data)
16    return response
17
18
19if __name__ == '__main__':
20    # 需要替换为实际的任务id
21    task_id = "task_id"
22    # {access_token} 需要替换为实际调用鉴权接口获取的access_token
23    request_host = "https://aip.baidubce.com/rest/2.0/brain/online/v2/parser/task/query?access_token={access_token}"
24    resp = query_task(request_host, task_id)
25    print(resp.json())
返回说明
返回参数
| 字段 | 类型 | 说明 |
|---|---|---|
| log_id | uint64 | 唯一的log id,用于问题定位 |
| error_code | int | 错误码 |
| error_msg | string | 错误描述信息 |
| result | dict | 返回的结果列表 |
| + task_id | string | 任务ID |
| + status | string | 任务状态,pending:排队中;running:运行中;success:成功;failed:失败 |
| + task_error | string | 解析报错信息,包含任务失败、额度不够 |
| + markdown_url | string | 文档解析结果的markdown格式链接,链接有效期30天 |
| + parse_result_url | string | 文档解析结果的Json链接,链接有效期30天 |
| + pdf_file_url | string | 整份 PDF,仅 need_pdffile_data=true 且 success 时下发,有效期 30 天。未开启时没有该字段。 新增 |
| + cost_page_num | int | 任务解析页数,即该任务对应的消耗额度 |
可通过parse_result_url下载解析结果的JSON文件,parse_result_url的返回参数如下:
| 字段 | 类型 | 说明 |
|---|---|---|
| file_name | string | 文档名称 |
| file_id | string | 文档ID |
| + pages | list | 文件单页解析内容 |
| ++ page_id | string | 页码ID |
| ++ page_num | int | 页码数,从0开始 |
| ++ text | string | 当前页的所有纯文字内容,含表格 Markdown |
| ++ layouts | list | 页面内容版式分析的结果 |
| +++ layout_id | string | layout ID,layout元素唯一标志,以"xxxxx-layout-{global_layout_index}"形式,global_layout_index为layout元素整个文档的全局索引 |
| +++ text | string | layout对应的文本内容。注:当type为table, image时该字段为空, 需要根据type和layout_id分别到tables, images字段里找到对应的内容 |
| +++ position | list | layout元素在页面中的位置,[x, y, w, h] box框,左上角和宽高 |
| +++ type | string | layout元素类型, 当前可取值: • text:段落 • table:表格 • head_tail:页面顶部 • image:文档中的插图 • contents:目录 • seal:印章 • title:标题 • formula:公式 • hand_sign:手写签名 |
| +++ sub_type | string | layout元素子类型, 当type为title、image时,subtype有值。 title类的 subtype 包含: • title_{n},代表n级标题, 比如title_2代表二级标题 • image_title:图标题 • table_title:表标题 image类的 subtype 包含: • chart:统计图表 • figure:普通插图 • QR_code:二维码 • Bar_code:条形码 |
| +++ parent | string | 标题层级树中父节点的layout ID,若当前layout为一级标题,其parent为 "root"。在table和image的内嵌版面信息中暂时都为空 |
| +++ children | list | 标题层级树中子节点的layout ID。在table和image的内嵌版面信息中暂时都为空 |
| ++ tables | list | 页面表格解析结果 |
| +++ layout_id | string | layout ID,与layouts中的元素type为table的元素的layout ID对应 |
| +++ markdown | string | 表格内容的markdown形式 |
| +++ html | string | 表格 HTML,html_table_format=true(默认)时有值 |
| +++ table_title_id | list | 表格标题对应的layout_id,默认为null |
| +++ position | list | 边框数据 「x, y, w, h」(x, y)为坐标点坐标,w为box宽度,h为box高度(以页面坐标为原点),版式格式时有效 |
| +++ cells | list | 单元格的内嵌版面信息,layout类型为表格时有值 |
| +++ matrix | list | 二位数组 表示表格内布局位置信息,每个元素对应cells列表中元素的索引 |
| +++ merge_table | string | 默认开启,「begin」- 跨页表格开始、「inner」- 跨页表格中间表格(表格跨页超过两页)、「end」- 跨页表格结束;非跨页表格该字段为空 |
| ++ images | list | 页面中图片解析结果 |
| +++ layout_id | string | layout ID,与layouts中的元素type为image的元素的layout ID对应 |
| +++ image_title_id | list | 图片标题对应的layout_id,默认为null |
| +++ position | list | 边框数据 「x, y, w, h」(x, y)为坐标点坐标,w为box宽度,h为box高度(以页面坐标为原点),版式格式时有效 |
| +++ content_layouts | list | 图片的内嵌版面信息 |
| +++ data_url | string | 图片存储链接,有效期 30 天 |
| +++ image_description | string | 对统计图表进行内容解析和描述,输出结果为json字符串,可通过json.loads结构化为json格式 |
| ++ meta | dict | 页面元信息 |
| +++ page_width | int | 页面宽度 |
| +++ page_height | int | 页面高度 |
| +++ is_scan | bool | 是否扫描件 |
| +++ page_angle | int | 页面倾斜角度 |
| +++ page_type | string | 页面属性,包括:「text」-正文、「contents」-目录、「appendix」-附录、[doc]-含有文档插图、[seal]签章页、「others」-其他 |
| +++ sheet_name | string | excel的sheet名 |
| + chunks | list | 文件内容切分结果,return_doc_chunks中switch为True时有值 |
| ++ chunk_id | string | 切片的ID |
| ++ content | string | 切片的内容 |
| ++ type | string | 切片类型, 为text或者table |
| ++ meta | dict | chunk元信息 |
| +++ title | list | chunk所属的多级标题内容 |
| +++ position | list | chunk的位置,根据分块算法有可能chunk跨多个页 |
| +++ box | list | chunk的位置坐标 |
| +++ page_num | int | chunk内容所在页数 |
返回示例
示例文件:
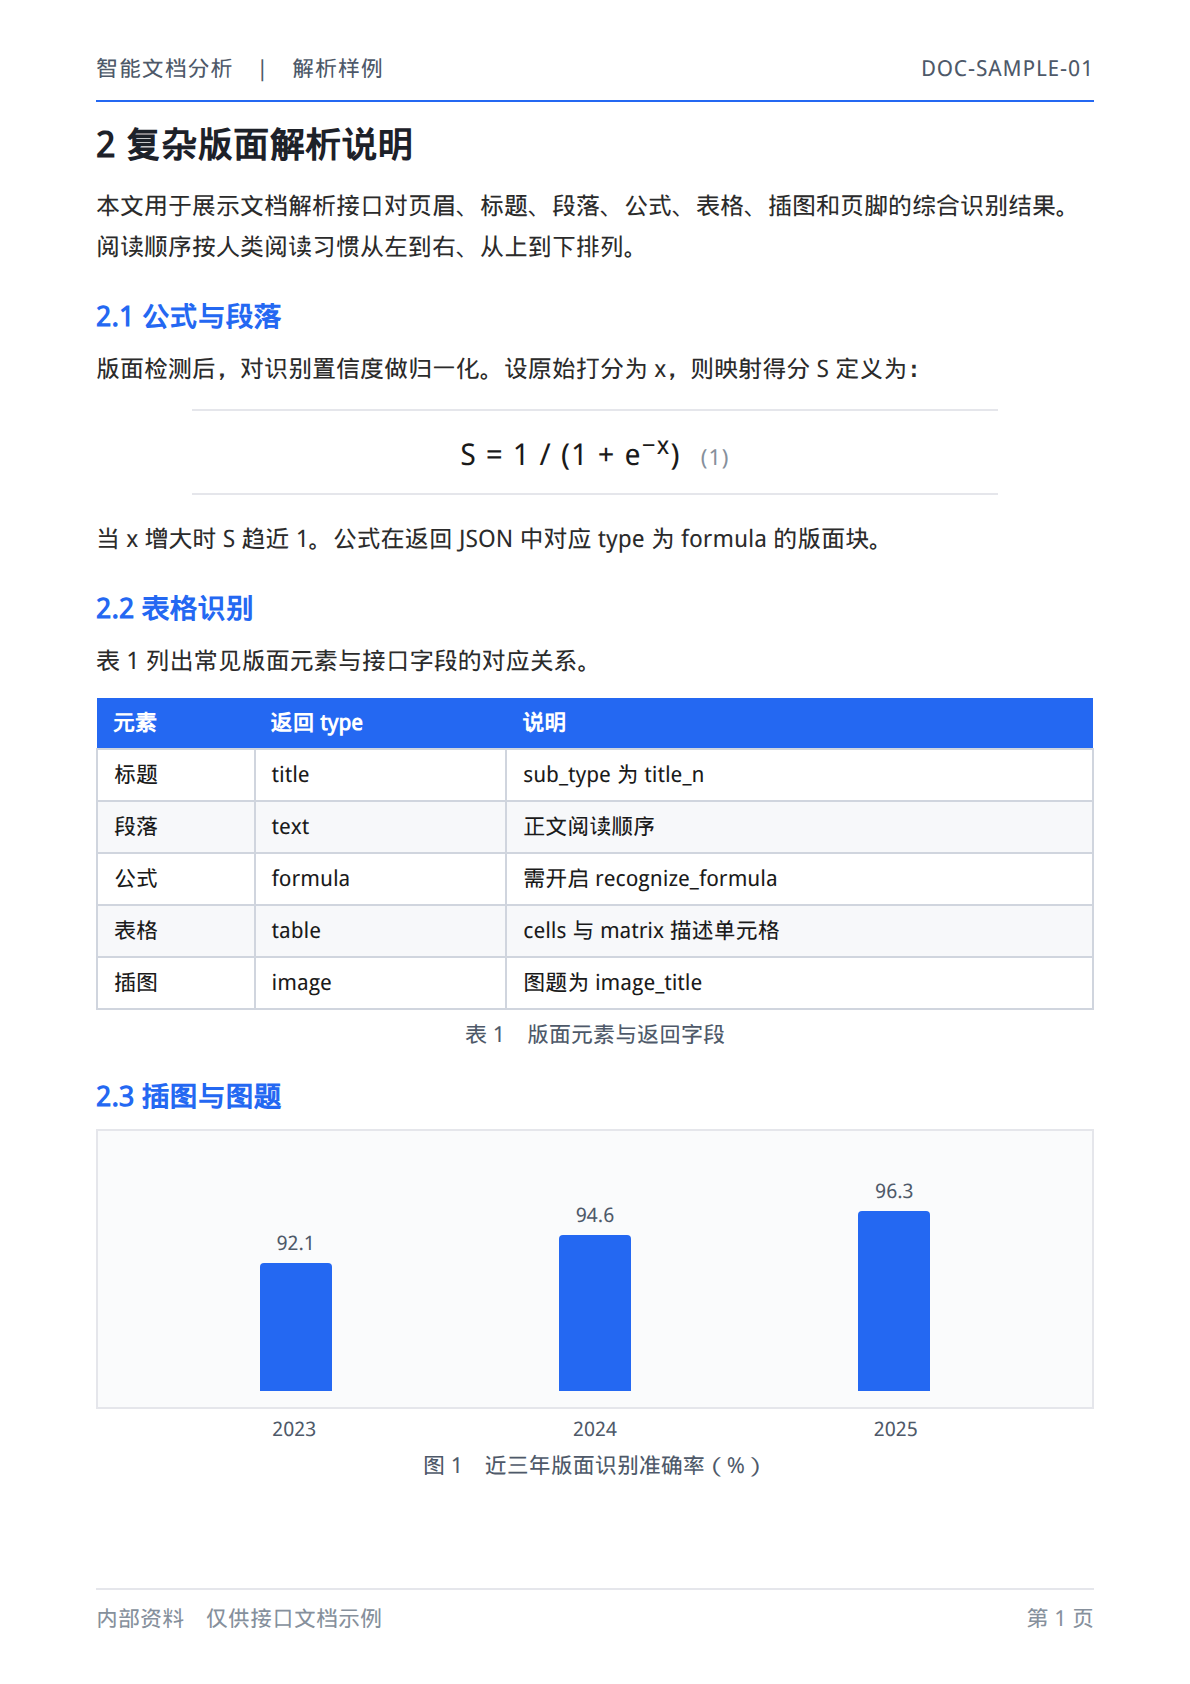
成功返回示例:
1{
2    "log_id": "23596597899286921761579365582373",
3    "error_code": 0,
4    "error_msg": "",
5    "result":
6    {
7        "task_id": "task-UnvGsgbYZp9pS3BZRHn11ifzjNvKzTgf",
8        "status": "success",
9        "task_error": null,
10        "duration": 902.0,
11        "parse_result_url": "https:xxxxxxxxxxxxxxxxxxx"
12    }
13}
解析结果示例:
1{
2    "file_name": "文档解析样例页.png",
3    "file_id": "file-u9kVDu6dtwMyNrizbejMlF8A852aJLm2",
4    "pages": [
5        {
6            "page_id": "2aJLm2-page-0",
7            "page_num": 0,
8            "text": "智能文档分析 | 解析样例\n2 复杂版面解析说明\n本文用于展示文档解析接口对页眉、标题、段落、公式、表格、插图和页脚的综合识别结果。阅读顺序按人类阅读习惯从左到右、从上到下排列。\n2.1 公式与段落\n版面检测后,对识别置信度做归一化。设原始打分为 x,则映射得分 S 定义为:\nS = 1 / (1 + e^{-x})\n当 x 增大时 S 趋近 1。公式在返回 JSON 中对应 type 为 formula 的版面块。\n2.2 表格识别\n表 1 列出常见版面元素与接口字段的对应关系。\n| 元素 | 返回 type | 说明 |\n| --- | --- | --- |\n| 标题 | title | sub_type 为 title_n |\n| 段落 | text | 正文阅读顺序 |\n| 公式 | formula | 需开启 recognize_formula |\n| 表格 | table | cells 与 matrix 描述单元格 |\n| 插图 | image | 图题为 image_title |\n表 1 版面元素与返回字段\n2.3 插图与图题\n图 1 近三年版面识别准确率(%)\n内部资料 仅供接口文档示例\n第 1 页\n",
9            "layouts": [
10                {
11                    "layout_id": "2aJLm2-layout-1",
12                    "text": "智能文档分析 | 解析样例",
13                    "position": [48, 28, 499, 22],
14                    "type": "head_tail",
15                    "sub_type": "",
16                    "parent": "root",
17                    "children": []
18                },
19                {
20                    "layout_id": "2aJLm2-layout-2",
21                    "text": "2 复杂版面解析说明",
22                    "position": [48, 62, 220, 24],
23                    "type": "title",
24                    "sub_type": "title_1",
25                    "parent": "root",
26                    "children": ["2aJLm2-layout-3", "2aJLm2-layout-4", "2aJLm2-layout-9", "2aJLm2-layout-13"]
27                },
28                {
29                    "layout_id": "2aJLm2-layout-3",
30                    "text": "本文用于展示文档解析接口对页眉、标题、段落、公式、表格、插图和页脚的综合识别结果。阅读顺序按人类阅读习惯从左到右、从上到下排列。",
31                    "position": [48, 92, 499, 40],
32                    "type": "text",
33                    "sub_type": "",
34                    "parent": "2aJLm2-layout-2",
35                    "children": []
36                },
37                {
38                    "layout_id": "2aJLm2-layout-4",
39                    "text": "2.1 公式与段落",
40                    "position": [48, 140, 140, 20],
41                    "type": "title",
42                    "sub_type": "title_2",
43                    "parent": "2aJLm2-layout-2",
44                    "children": ["2aJLm2-layout-5", "2aJLm2-layout-6", "2aJLm2-layout-7"]
45                },
46                {
47                    "layout_id": "2aJLm2-layout-5",
48                    "text": "版面检测后,对识别置信度做归一化。设原始打分为 x,则映射得分 S 定义为:",
49                    "position": [48, 164, 499, 36],
50                    "type": "text",
51                    "sub_type": "",
52                    "parent": "2aJLm2-layout-4",
53                    "children": []
54                },
55                {
56                    "layout_id": "2aJLm2-layout-6",
57                    "text": "S = 1 / (1 + e^{-x})",
58                    "position": [96, 208, 400, 36],
59                    "type": "formula",
60                    "sub_type": "",
61                    "parent": "2aJLm2-layout-4",
62                    "children": []
63                },
64                {
65                    "layout_id": "2aJLm2-layout-7",
66                    "text": "当 x 增大时 S 趋近 1。公式在返回 JSON 中对应 type 为 formula 的版面块。",
67                    "position": [48, 252, 499, 20],
68                    "type": "text",
69                    "sub_type": "",
70                    "parent": "2aJLm2-layout-4",
71                    "children": []
72                },
73                {
74                    "layout_id": "2aJLm2-layout-9",
75                    "text": "2.2 表格识别",
76                    "position": [48, 284, 140, 20],
77                    "type": "title",
78                    "sub_type": "title_2",
79                    "parent": "2aJLm2-layout-2",
80                    "children": ["2aJLm2-layout-10", "2aJLm2-layout-11", "2aJLm2-layout-12"]
81                },
82                {
83                    "layout_id": "2aJLm2-layout-10",
84                    "text": "表 1 列出常见版面元素与接口字段的对应关系。",
85                    "position": [48, 308, 499, 18],
86                    "type": "text",
87                    "sub_type": "",
88                    "parent": "2aJLm2-layout-9",
89                    "children": []
90                },
91                {
92                    "layout_id": "2aJLm2-layout-11",
93                    "text": "",
94                    "position": [48, 330, 499, 148],
95                    "type": "table",
96                    "sub_type": "",
97                    "parent": "2aJLm2-layout-9",
98                    "children": []
99                },
100                {
101                    "layout_id": "2aJLm2-layout-12",
102                    "text": "表 1 版面元素与返回字段",
103                    "position": [48, 484, 200, 16],
104                    "type": "title",
105                    "sub_type": "table_title",
106                    "parent": "2aJLm2-layout-9",
107                    "children": []
108                },
109                {
110                    "layout_id": "2aJLm2-layout-13",
111                    "text": "2.3 插图与图题",
112                    "position": [48, 512, 140, 20],
113                    "type": "title",
114                    "sub_type": "title_2",
115                    "parent": "2aJLm2-layout-2",
116                    "children": ["2aJLm2-layout-14", "2aJLm2-layout-15"]
117                },
118                {
119                    "layout_id": "2aJLm2-layout-14",
120                    "text": "",
121                    "position": [48, 536, 499, 140],
122                    "type": "image",
123                    "sub_type": "chart",
124                    "parent": "2aJLm2-layout-13",
125                    "children": []
126                },
127                {
128                    "layout_id": "2aJLm2-layout-15",
129                    "text": "图 1 近三年版面识别准确率(%)",
130                    "position": [48, 682, 240, 16],
131                    "type": "title",
132                    "sub_type": "image_title",
133                    "parent": "2aJLm2-layout-13",
134                    "children": []
135                },
136                {
137                    "layout_id": "2aJLm2-layout-16",
138                    "text": "内部资料 仅供接口文档示例",
139                    "position": [48, 800, 220, 14],
140                    "type": "head_tail",
141                    "sub_type": "",
142                    "parent": "root",
143                    "children": []
144                },
145                {
146                    "layout_id": "2aJLm2-layout-17",
147                    "text": "第 1 页",
148                    "position": [500, 800, 48, 14],
149                    "type": "head_tail",
150                    "sub_type": "",
151                    "parent": "root",
152                    "children": []
153                }
154            ],
155            "tables": [
156                {
157                    "layout_id": "2aJLm2-layout-11",
158                    "markdown": "| 元素 | 返回 type | 说明 |\n| --- | --- | --- |\n| 标题 | title | sub_type 为 title_n |\n| 段落 | text | 正文阅读顺序 |\n| 公式 | formula | 需开启 recognize_formula |\n| 表格 | table | cells 与 matrix 描述单元格 |\n| 插图 | image | 图题为 image_title |\n",
159                    "html": "<table><thead><tr><th>元素</th><th>返回 type</th><th>说明</th></tr></thead><tbody><tr><td>标题</td><td>title</td><td>sub_type 为 title_n</td></tr><tr><td>段落</td><td>text</td><td>正文阅读顺序</td></tr><tr><td>公式</td><td>formula</td><td>需开启 recognize_formula</td></tr><tr><td>表格</td><td>table</td><td>cells 与 matrix 描述单元格</td></tr><tr><td>插图</td><td>image</td><td>图题为 image_title</td></tr></tbody></table>",
160                    "table_title_id": ["2aJLm2-layout-12"],
161                    "position": [48, 330, 499, 148],
162                    "cells": [
163                        {"layout_id": "2aJLm2-layout-11-0", "text": "元素", "position": [48, 330, 80, 24], "type": "text", "sub_type": "", "parent": "", "children": null},
164                        {"layout_id": "2aJLm2-layout-11-1", "text": "返回 type", "position": [128, 330, 120, 24], "type": "text", "sub_type": "", "parent": "", "children": null},
165                        {"layout_id": "2aJLm2-layout-11-2", "text": "说明", "position": [248, 330, 299, 24], "type": "text", "sub_type": "", "parent": "", "children": null},
166                        {"layout_id": "2aJLm2-layout-11-3", "text": "标题", "position": [48, 354, 80, 24], "type": "text", "sub_type": "", "parent": "", "children": null},
167                        {"layout_id": "2aJLm2-layout-11-4", "text": "title", "position": [128, 354, 120, 24], "type": "text", "sub_type": "", "parent": "", "children": null},
168                        {"layout_id": "2aJLm2-layout-11-5", "text": "sub_type 为 title_n", "position": [248, 354, 299, 24], "type": "text", "sub_type": "", "parent": "", "children": null}
169                    ],
170                    "matrix": [
171                        [0, 1, 2],
172                        [3, 4, 5],
173                        [6, 7, 8],
174                        [9, 10, 11],
175                        [12, 13, 14],
176                        [15, 16, 17]
177                    ],
178                    "merge_table": ""
179                }
180            ],
181            "images": [
182                {
183                    "layout_id": "2aJLm2-layout-14",
184                    "image_title_id": ["2aJLm2-layout-15"],
185                    "position": [48, 536, 499, 140],
186                    "content_layouts": [],
187                    "data_url": "https://bj.bcebos.com/v1/example/2aJLm2-layout-14.png",
188                    "image_description": ""
189                }
190            ],
191            "meta": {
192                "page_width": 595,
193                "page_height": 842,
194                "is_scan": false,
195                "page_angle": 0,
196                "page_type": "doc",
197                "sheet_name": ""
198            }
199        }
200    ],
201    "chunks": [
202        {
203            "chunk_id": "2aJLm2-chunk-0",
204            "content": "版面检测后,对识别置信度做归一化。设原始打分为 x,则映射得分 S 定义为:\nS = 1 / (1 + e^{-x})\n当 x 增大时 S 趋近 1。公式在返回 JSON 中对应 type 为 formula 的版面块。",
205            "type": "text",
206            "meta": {
207                "title": ["2 复杂版面解析说明", "2.1 公式与段落"],
208                "position": [{"box": [48, 164, 499, 108], "page_num": 0}]
209            }
210        },
211        {
212            "chunk_id": "2aJLm2-chunk-1",
213            "content": "| 元素 | 返回 type | 说明 |\n| --- | --- | --- |\n| 标题 | title | sub_type 为 title_n |\n| 段落 | text | 正文阅读顺序 |\n| 公式 | formula | 需开启 recognize_formula |\n| 表格 | table | cells 与 matrix 描述单元格 |\n| 插图 | image | 图题为 image_title |\n",
214            "type": "table",
215            "meta": {
216                "title": ["2 复杂版面解析说明", "2.2 表格识别"],
217                "position": [{"box": [48, 330, 499, 148], "page_num": 0}]
218            }
219        }
220    ]
221}
对应 Markdown(markdown_url)形态:
1# 2 复杂版面解析说明
2
3本文用于展示文档解析接口对页眉、标题、段落、公式、表格、插图和页脚的综合识别结果。阅读顺序按人类阅读习惯从左到右、从上到下排列。
4
5## 2.1 公式与段落
6
7版面检测后,对识别置信度做归一化。设原始打分为 x,则映射得分 S 定义为:
8
9$$
10S = 1 / (1 + e^{-x})
11$$
12
13当 x 增大时 S 趋近 1。公式在返回 JSON 中对应 type 为 formula 的版面块。
14
15## 2.2 表格识别
16
17表 1 列出常见版面元素与接口字段的对应关系。
18
19| 元素 | 返回 type | 说明 |
20| --- | --- | --- |
21| 标题 | title | sub_type 为 title_n |
22| 段落 | text | 正文阅读顺序 |
23| 公式 | formula | 需开启 recognize_formula |
24| 表格 | table | cells 与 matrix 描述单元格 |
25| 插图 | image | 图题为 image_title |
26
27## 2.3 插图与图题
28
29页眉页脚会出现在 JSON 的 head_tail 里,默认不进 Markdown 正文。
常见错误码
完整列表见 错误码。接入时至少处理:
| error_code | 含义 |
| 0 | 成功 |
| 282003 | 缺参数 |
| 282007 | task_id 不存在或已过期 |
评价此篇文章